What browser-side processing means
Many traditional online tools upload a file to a remote server, process it there and return the result. Browser-side processing moves some or all of that work to the user's own device. The selected file is read by code running in the browser rather than being transmitted to an application server for the transformation.
JavaScript, Canvas, WebAssembly and modern browser file APIs make it possible to resize images, manipulate PDFs, count text, decode QR codes and perform many other operations locally.
How local processing can improve privacy
If a file does not need to leave the device for processing, there is less exposure created by network transmission, temporary server storage and application-side logging. That can be valuable for documents that contain personal or business information.
Local processing can also improve speed. A user does not have to upload a 50 MB file merely to rotate a page or resize an image, and the result can often be produced immediately after the browser finishes the computation.
Local processing does not mean zero network activity
This distinction is important. A website can process your selected file locally while still loading fonts, analytics, scripts or libraries from remote servers. The statement 'your file is processed in the browser' is more precise than claiming that the entire page works without any network connections.
Good privacy communication explains what happens to the file itself and avoids making broader promises that the implementation cannot support.
Browser processing vs server processing
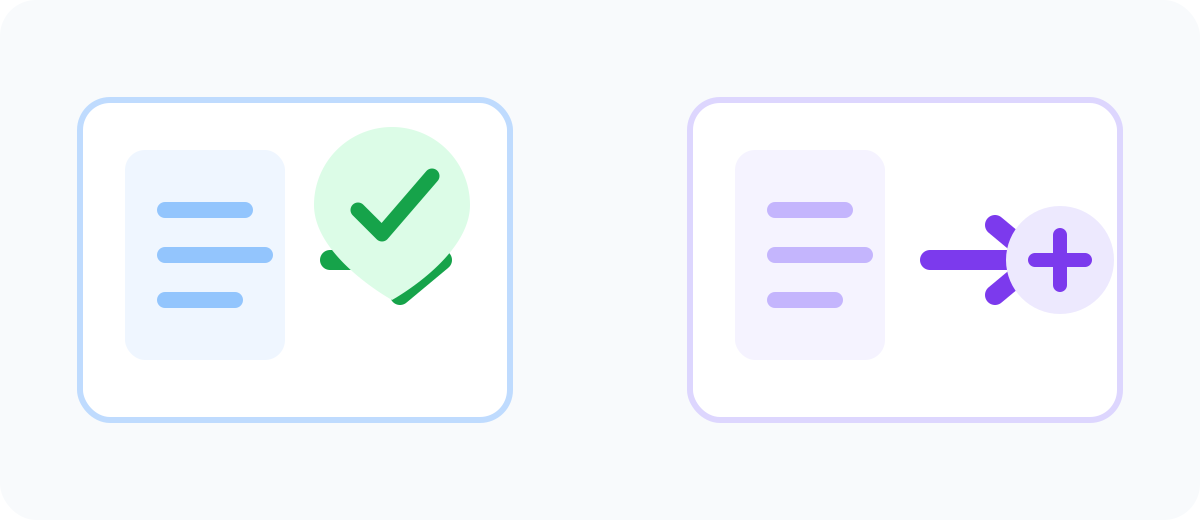
Server processing has advantages. Powerful servers can handle very large files, intensive OCR jobs, complex conversions and advanced AI models that would be slow on a low-end phone. Server workflows can also support collaboration and persistent storage.
Browser processing is attractive when the task is self-contained and the user's device can handle it. The best architecture depends on the job rather than a rule that everything must always be local.
- Browser: less file transfer and often faster for small tasks
- Browser: uses the user's CPU, memory and battery
- Server: better for heavy computation and very large files
- Server: requires clear upload, retention and privacy policies
What WebAssembly changes
WebAssembly allows software compiled from languages such as C or Rust to run inside modern browsers at near-native speed for many workloads. This makes complex document and image processing possible without installing desktop software.
The trade-off is that the browser may need to download a larger processing module before the first use. For some tools, that initial download is worthwhile because later work can remain on the user's device.
Performance limits on phones and older computers
Local processing uses the resources of the device in front of you. A large PDF can consume significant memory, and image or document operations can temporarily make a browser tab feel slow. Battery-powered devices may also use more energy during intensive processing.
Good tools should communicate progress, avoid unnecessary copies of large files in memory and provide reasonable limits when an operation could overwhelm a device.
What to check before using an online file tool
For ordinary files, convenience may be enough. For sensitive material, spend a minute checking how the tool describes its processing model and data handling. Clear documentation is a better sign than vague claims such as '100% secure' with no explanation.
- Does the tool say whether file processing is local or remote?
- If files are uploaded, how long are they retained?
- Is the site served over HTTPS?
- Is an account required?
- Are third-party services involved?
- Would approved offline software be safer for this particular file?
When local processing is especially useful
Simple transformations are ideal candidates: counting text, resizing an image, converting common image formats, rotating PDF pages or reading a QR image. These jobs can often be completed without a server seeing the selected file.
The result is not only a privacy improvement. It can reduce server costs and make a free tool more sustainable because the user's device performs the computation.
A practical privacy mindset
No single architecture makes every risk disappear. Local processing reduces some categories of exposure, but users should still protect their devices, browser accounts and sensitive files. Websites should make accurate claims, minimize unnecessary data collection and explain exceptions clearly.
For a privacy-first utility site, the goal is simple: process locally when practical, disclose when a task requires something else, and avoid collecting information that is not needed to complete the user's task.